Malhar
Khisty
About Me
Hi, I’m Malhar.
I enjoy building thoughtful digital experiences and exploring the ideas where design, software, and technology meet.
Selected Work
Projects
SvelteKit / Node.js / Solidity · 2026
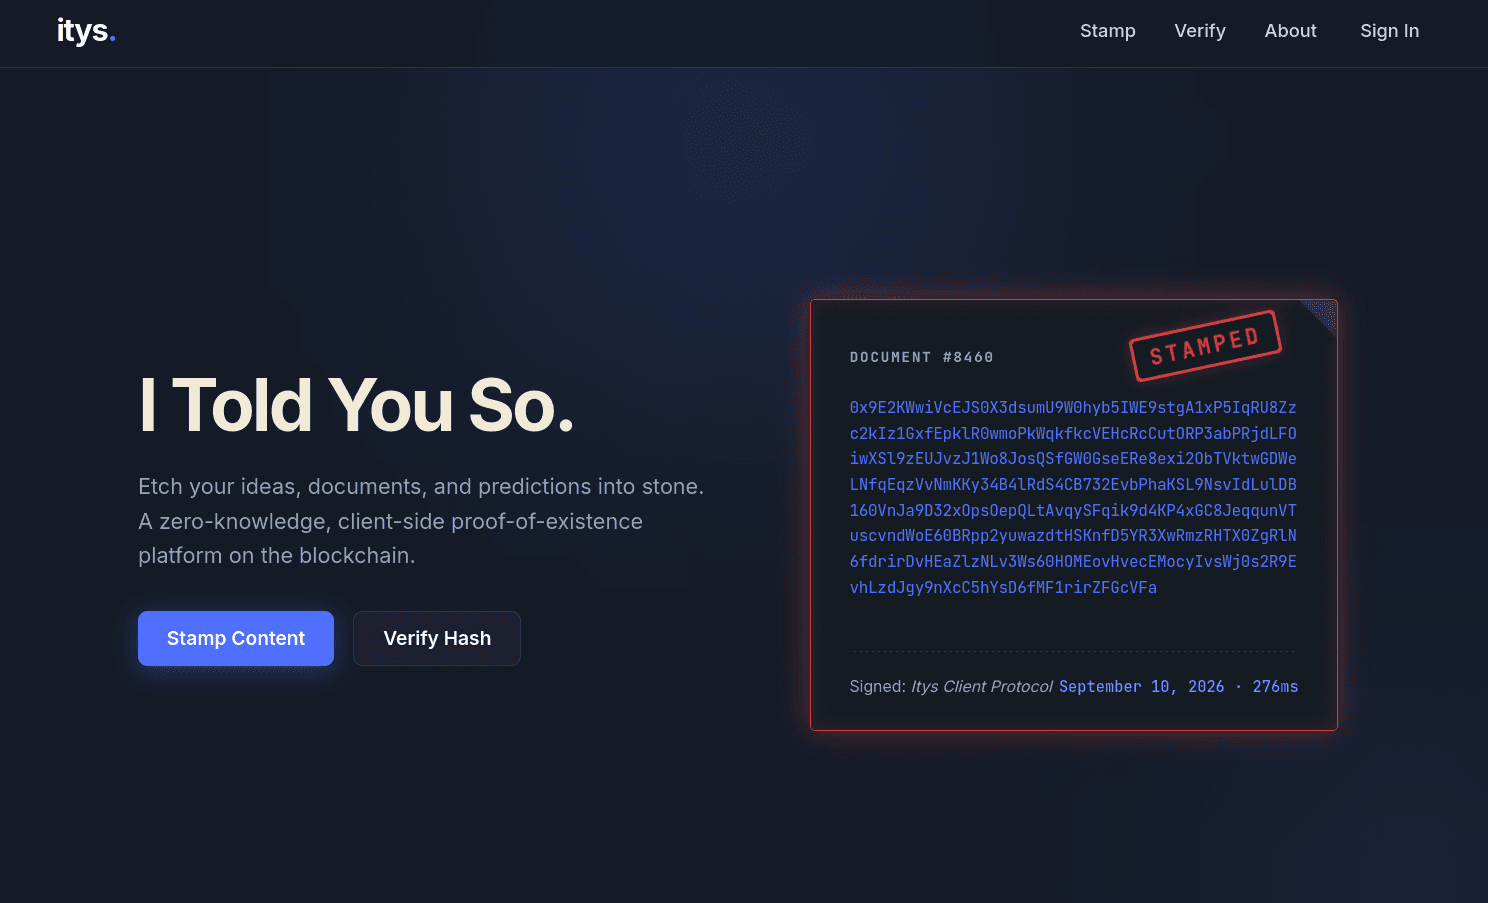
Itys
Private, verifiable proofs of existence.
View details →
Rust CLI · 2026
Slipspace
Local-speed development on remote compute.
View details →
C++ / Python · 2025
redCedar
A lightweight machine-learning framework built from scratch in C++, with Python bindings for constructing and training neural networks.
View details →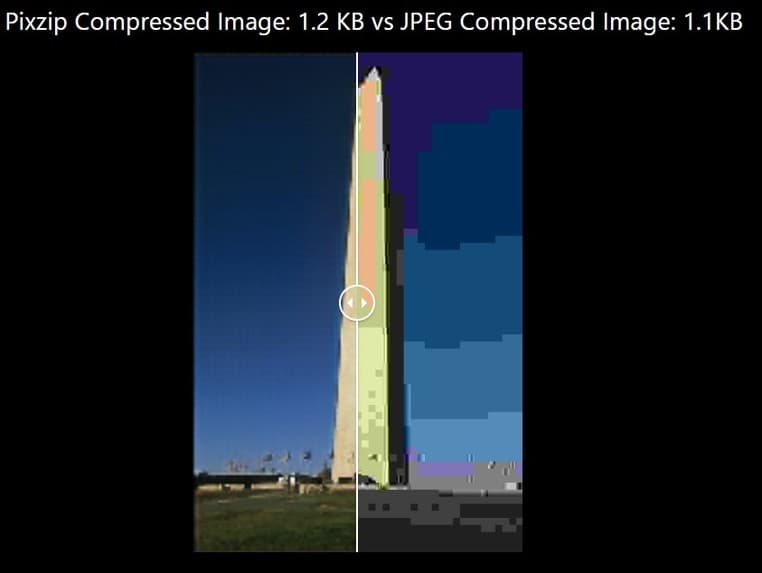
PyTorch GAN · 2024
Pixzip
A generative image-compression model that extracts the most useful visual information and reduces image data by up to 93%.
View details →
Next.js / NestJS / Python
BaitBlock
Email-based phishing detection and tracker removal.
View details →Next.js / Three.js · 2026
This Portfolio
Built with Next.js, React, Three.js, and data-driven JSON content.
View details →Background
Experience
Software Engineering Intern · May–August 2026
University of Michigan ITS
Built enterprise backend services, data integrations, and internal AI tools for University of Michigan ITS at the Ross School of Business.
View details →
Research · June 2025–Present
Research Assistant
Developing high-performance biological simulation and representation-learning systems for complex physiological models.
View details →
Software Lead · December 2024–Present
DRIFT
Leading software development for a NASA-recognized autonomous tethered drone that inspects aircraft airframes using eddy currents.
View details →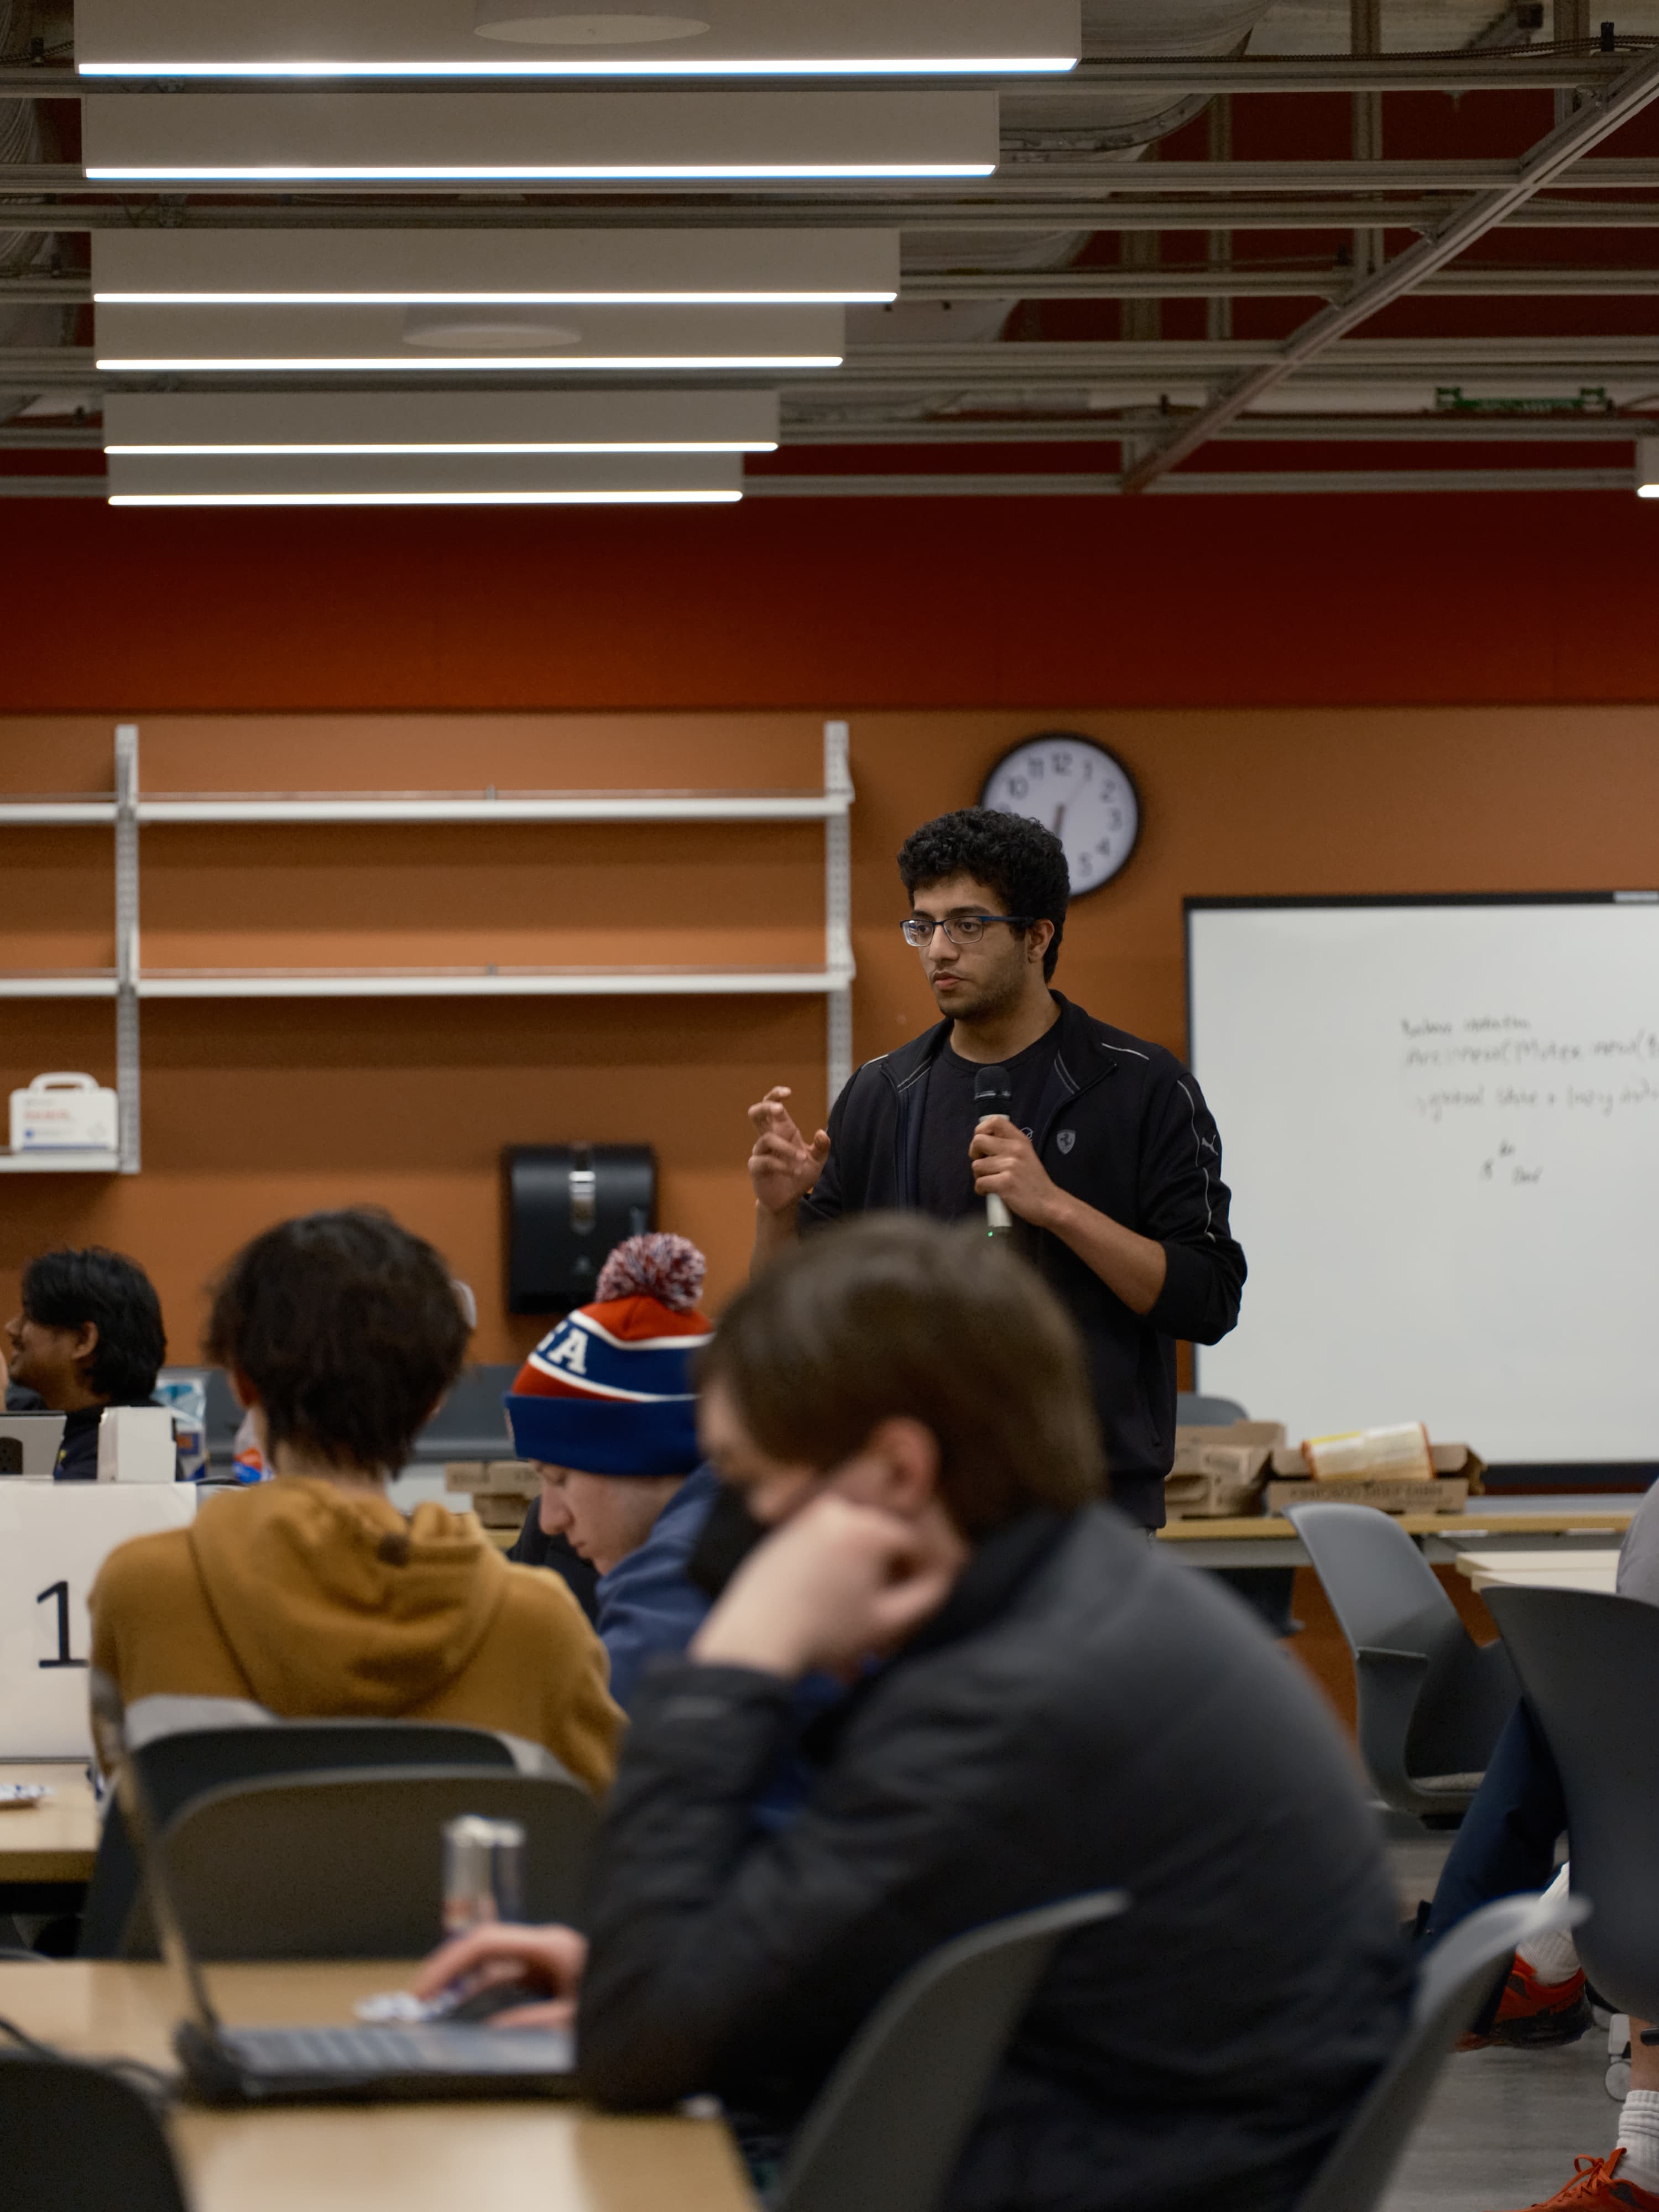
Workshop Director · Involvement
AI Club
Led weekly machine-learning workshops covering modern AI topics for more than 150 attendees.
View details →
Finance Lead · Involvement
SpartaHack
Raised $40,000 for an MLH hackathon through industry outreach, negotiation, and sponsor relationships.
View details →Inquiry
Research
Publications
Articles
Independent work that wasnt published, but has valuable insight.
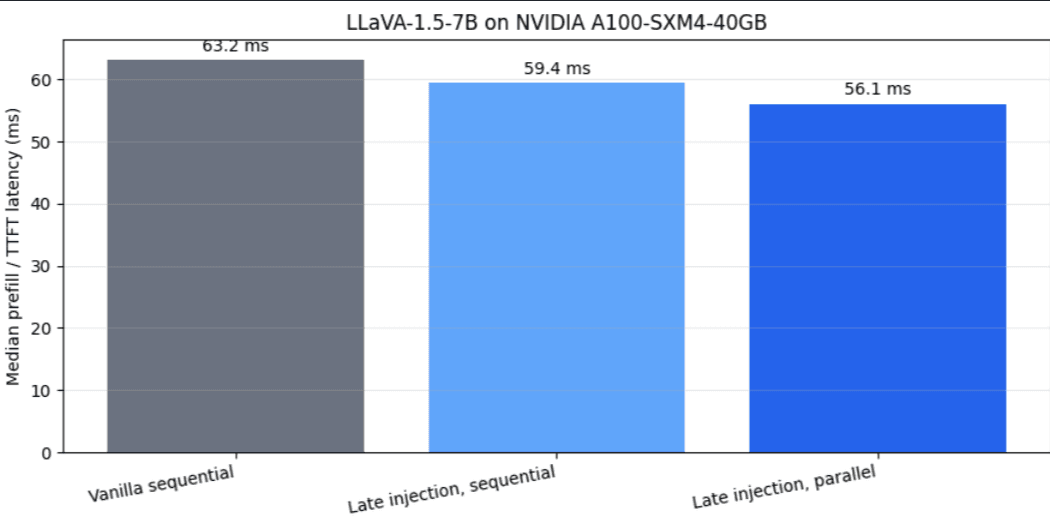
Speeding up VLM inference with late token insertion
An exploration of delaying selected visual tokens until they are needed, reducing wasted computation while preserving the model’s useful context.
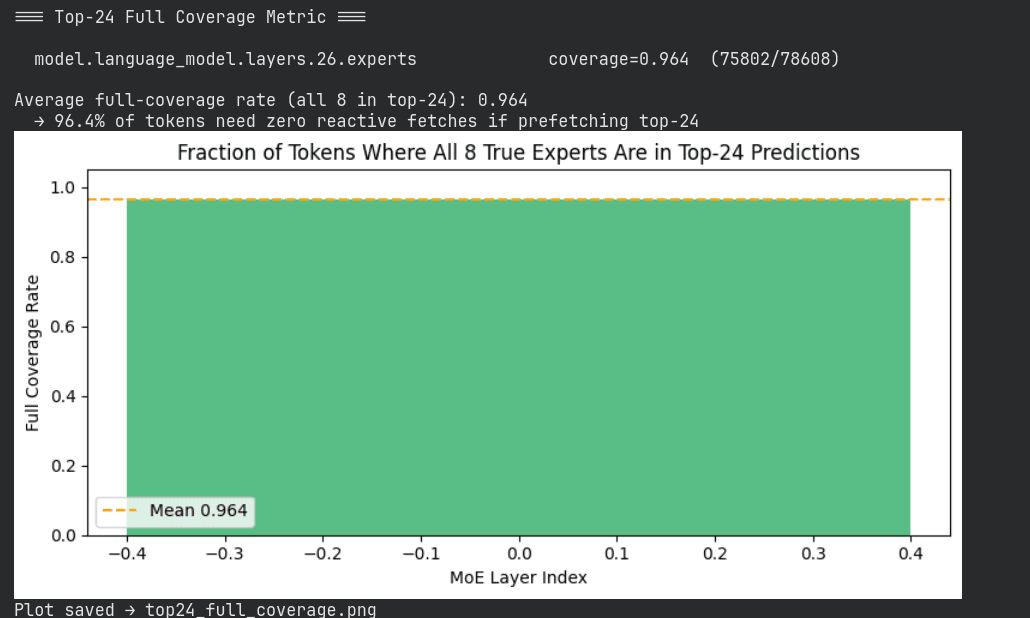
Reducing VRAM footprint of MoE LLMs through predictive loading
A study of predicting which experts will be activated so model weights can be staged just ahead of demand instead of remaining resident in VRAM.