Inquiry
Research
Research
Publications
Incoming
Research
Articles
Independent work that wasnt published, but has valuable insight.
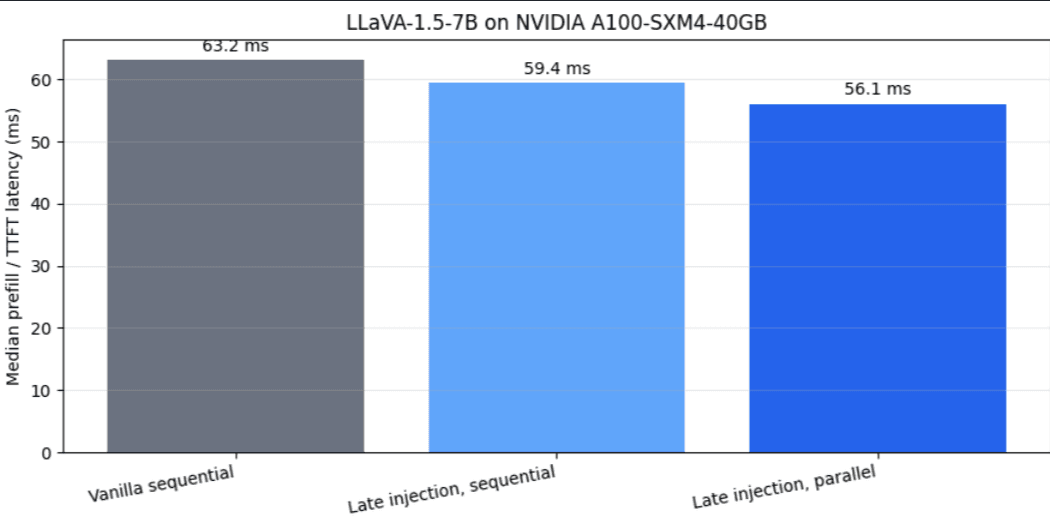
Vision-Language Models · Draft
Speeding up VLM inference with late token insertion
An exploration of delaying selected visual tokens until they are needed, reducing wasted computation while preserving the model’s useful context.
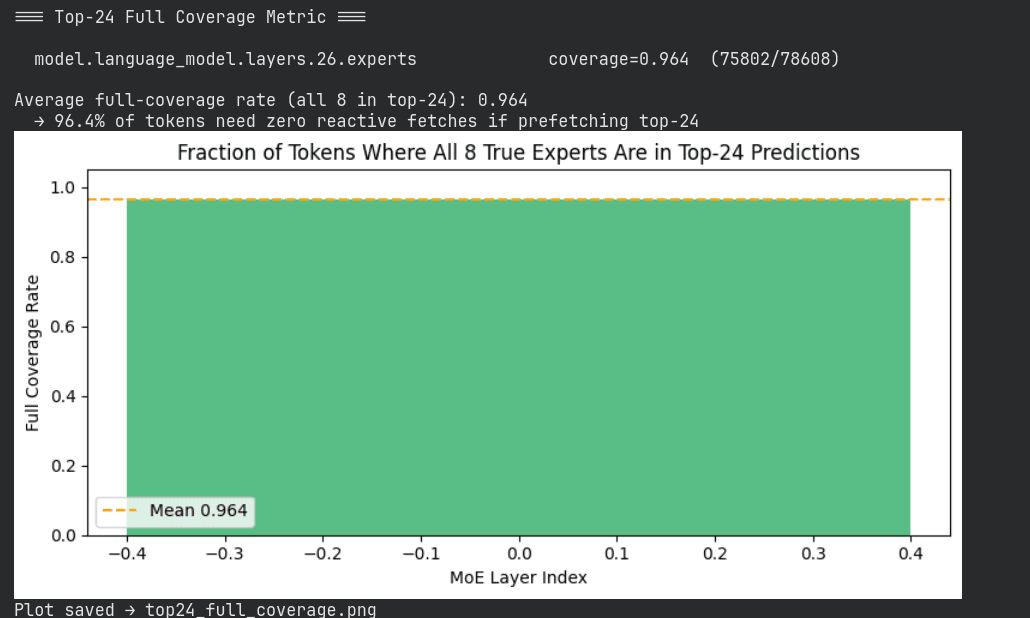
Mixture-of-Experts
Reducing VRAM footprint of MoE LLMs through predictive loading
A study of predicting which experts will be activated so model weights can be staged just ahead of demand instead of remaining resident in VRAM.